 Syntheta AI
Capture once. Train every condition.
Syntheta is the foundation model for physical AI training data. Pre-trained on the world's factory and robotics datasets, it generates unlimited, customer-specific, real-indistinguishable training data on demand.
From one real capture.
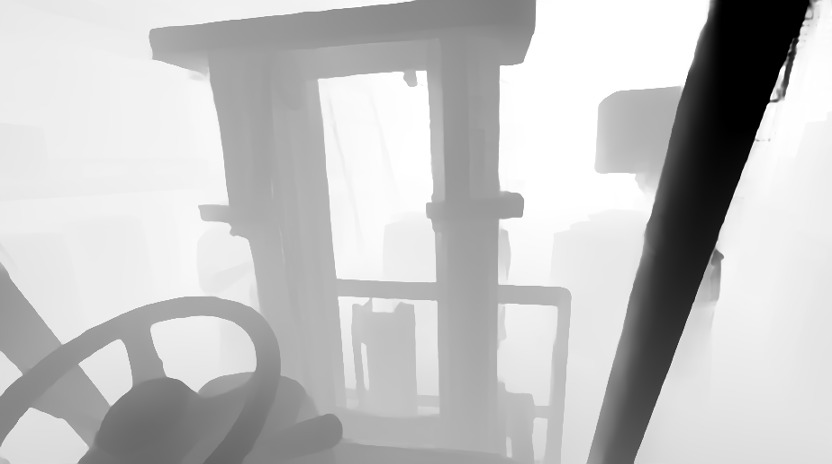
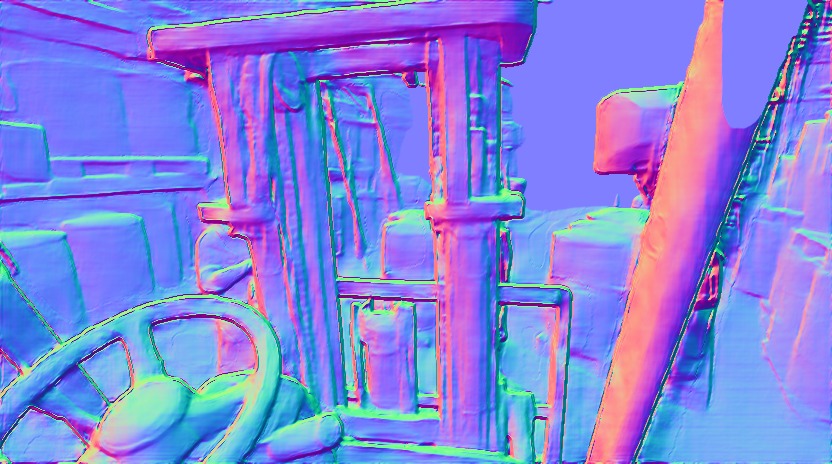
Depth and surface structure estimated from a single factory capture.
Real capture is the bottleneck.
Collecting every operating condition in the real world is slow and often unsafe. Syntheta expands the footage you already have into labeled training data for the cases that are hardest to collect: low light, motion, occlusion, and new viewpoints.
Every generated frame stays anchored to the original scene. Labels and provenance carry through each variant, so your team can inspect the data, trust it, and train on it.
Bring a real capture
Factory, robot, or drone footage you already own.
Define the conditions
Lighting, motion, occlusion, sensor variation.
Generate and validate
New samples with labels and provenance carried forward.
Data you can train on.
Bring a real capture and your target classes. We return a validated dataset and a training baseline.